# Robin Dhiman
> Robin Dhiman has shipped production e-commerce systems for fifteen years, mostly Magento 2 and Hyvä, with extensions into Shopify, WordPress, and Next.js. He is currently building magento2-module-llms-txt — an open-source module that makes Magento catalogs discoverable by AI assistants like ChatGPT, Claude, and Perplexity — by emitting both an llms.txt index and an llms-full.txt content dump so AI agents can ingest a full catalog in one request instead of rate-limiting on per-product crawls.
Portfolio: https://devrob.in
Writing index: https://devrob.in/blog
Contact: hello@devrob.in
GitHub: https://github.com/iamrobindhiman
LinkedIn: https://www.linkedin.com/in/iamrobindhiman/
X: https://x.com/IAmRobinDhiman
---
Below: the full plain-text content of every post on devrob.in, newest first. Each entry begins with the post title as an H1, followed by a byline line (date · read time · author) and the post's canonical URL.
---
# A model's output is a lead, not a fact
_Published 2026-09-01 · 7 min · Robin Dhiman_
_URL: https://devrob.in/blog/a-models-output-is-a-lead-not-a-fact_
Someone posted about a conference where the AI use by academics was, in their words, absurd. The complaint lands. But "people are using AI badly" is not a useful finding on its own, because it doesn't tell you what using it well looks like.
I use AI for a large share of my engineering work. Not for autocomplete. For reviewing whole systems, for reading unfamiliar framework code, for finding the bug I can't see. It works. It also produces confident, well-argued, completely wrong output on a regular basis, and the difference between those two outcomes is almost never the prompt.
It's whether anybody checked.
## The rule
A model's finding is a lead, not a fact.
That sounds like a platitude until you've watched what happens when you skip it. Three cases from my own projects, all inside the last few months.
## Case one: two models, opposite answers, same question
I was reviewing a payment-splitting module before it went near production. Money movement, so I ran the review as multiple independent passes rather than one, each with its own focus, none of them seeing the others' output.
Two of those passes reached opposite conclusions on the same question: whether a credit memo's net amount cancelled out an over-refund of tax. One said the bug was real. One said it was defused.
Both arguments read as competent. Both cited specific behaviour. There was no way to pick a winner from the text, because the disagreement wasn't about logic. It was about an assumption neither of them had stated. One had silently assumed a line item with no tax on it.
The only thing that settled it was opening the framework's own source and reading the method that registers a refund against a memo item. The field in question is tax-exclusive. That one line of vendor code decided it. The bug was real.
What I want to draw out: neither model was being careless. The failure mode is subtler than hallucination. It's an unstated premise carried confidently through an otherwise sound chain of reasoning, and the only thing that dislodges it is ground truth.
## Case two: the green test suite that certified a worse bug
Different project, a personal finance tool that parses transaction alert emails.
A review pass flagged a minor cosmetic issue: HTML entities like ` ` sitting next to an amount were confusing the parser and pushing clean transactions into manual review. Genuinely minor. The fix is obvious: decode numeric entities before parsing.
So I decoded them. Roughly:
```js
text.replace(/&#(\d+);/g, (_, code) =>
String.fromCodePoint(Number(code))
)
```
Then I ran everything. Type check clean. Lint clean. 490 tests passing. Build fine.
`String.fromCodePoint` throws a `RangeError` on any value above `0x10FFFF`. An email containing `�`, a 91-byte message, throws out of the ingest function. And because the message stays in the mailbox, it throws again on every retry, forever. The feed stops. Not degrades. Stops.
A batch that should have taken three real transactions took one.
Every deterministic gate I own was green over that. They were green because they test the code I wrote against the inputs I imagined, and I had not imagined an integer larger than Unicode. The fix for a cosmetic annoyance had created something far worse than the annoyance.
It was caught by accident. A second review pass happened to still be running against the tree I'd just changed, and it read the new code.
The generalisation I took from it: **a fix is a change that has not been reviewed yet.** Re-running the test suite after a fix proves nothing about the class of defect that the test suite couldn't see in the first place. If a review found a problem in some area, the fix to that area needs the same review again, fresh, with no memory of the previous round.
## Case three: the brief was the only variable
This one is about how you ask, and it's the cleanest experiment I've accidentally run.
One review pass, one codebase, two deliberate trade-offs in the code. Both were decisions I'd made on purpose, with reasons. In the instructions I gave the reviewer, I explained the reasoning behind the first one and, through nothing but haste, left the second unexplained.
It skipped the first. Correctly. It had the rationale, it weighed it, it moved on.
It reported the second as a critical defect.
Same pass, same code, same model. The only difference was whether the *why* was in the brief. And if I'd acted on that critical without checking, I would have "fixed" a deliberate decision and reintroduced the thing it was there to prevent.
This is the part people miss when they complain about AI output quality. A reviewer with no context reports every deviation from the obvious as a defect, because from where it's standing that's exactly what a deviation looks like. Context is not a nicety in the prompt. It's the difference between a finding and a false alarm.
## What separates augmentation from laziness
Not effort. Not prompt engineering. Not model choice, though that matters at the margins.
It's whether there's a verification step that doesn't run through the same mind that produced the output.
Three things I actually do now:
**Re-read the cited code before acting on any finding.** Every time. `file:line` or it didn't happen. Roughly a third of what comes back doesn't survive this, and the ones that don't survive are often the most persuasively written.
**Go to the source for framework behaviour.** Not the docs, not the model's summary, not my own memory of how the ORM works. The vendor file. This resolved case one and would have caught the tax-exclusive assumption before either pass ran.
**Never let the author certify the work.** If the same context wrote the fix, it isn't in a position to judge the fix. A fresh pass with no memory of the conversation finds things the original never will, precisely because it doesn't share the assumptions.
## The uncomfortable bit
None of this is about AI, which is why the academics-at-a-conference complaint slightly misses.
A junior developer's pull request is a lead, not a fact. A vendor's changelog is a lead. A green test suite is a lead: case two is exactly that, five separate green gates over a defect that killed a production feed. My own confident recollection of how a framework behaves is a lead, and it's wrong often enough that I've stopped trusting it.
AI just makes leads cheap. It generates plausible-sounding claims at a rate no human process ever could, which means the verification step is now the bottleneck, and skipping it produces failure faster than it used to.
The people using it badly aren't using it too much. They're verifying too little, and the volume makes that visible in a way it never was before.
Do the checking. It's the whole job now.
---
_Source / further reading: https://lobste.rs/s/qn7jtv_
---
# What a minimal JS framework hands back to you
_Published 2026-08-07 · 7 min · Robin Dhiman_
_URL: https://devrob.in/blog/what-a-minimal-js-framework-hands-back-to-you_
Every few months someone publishes a minimal UI library in a few hundred lines of vanilla JavaScript and the comments split into the same two camps. One side says this is all anyone ever needed. The other says wait until you have a real application.
Both camps are arguing about the wrong thing. I've spent the last few years building Magento storefronts on Hyvä, which is that argument made real: no React, no Knockout, no RequireJS, just Alpine and Tailwind. The storefronts are fast. The bundle argument is settled and it was never very interesting.
What nobody writes about is the bill. When you remove a framework you don't just remove its bytes. You take back a set of responsibilities it was handling without telling you, and you get no warning about which ones. Here are the three that cost me the most time.
## 1. Initialisation timing becomes your problem
React owns the lifecycle. A component mounts, effects run, and if it renders you know it initialised. That link is so reliable you stop thinking of it as a feature.
A minimal setup breaks the link, and it breaks it deliberately, because initialising every interactive component on page load is exactly the cost you were trying to avoid. So components get deferred: registered now, initialised later, on some trigger.
Hyvä does this with an `x-defer` attribute. The markup is on the page, the component is registered, and Alpine doesn't touch it until the trigger fires. Great for a product page with a dozen interactive widgets below the fold.
The failure mode is nasty. I once had a configurable-product size picker render as a thin strip with the label and no options in it. No console errors. The component function was defined on `window`. The catalogue data was fine, five salable children, the attribute mapped correctly.
Everything you'd check to diagnose a bug came back clean, because it wasn't a bug. The component simply hadn't been woken up. Its trigger never fired in that layout. It was sitting there fully registered and completely inert.
That reads exactly like a data problem or a broken build. I checked the indexer. I checked the swatch attribute. I rebuilt static content twice. The actual answer was one attribute deciding *when*, and nothing in the failure told me timing was the axis to look at.
With React, "the component didn't render" and "the component didn't initialise" are the same event. Without it, they're two events, and only one of them leaves evidence. Add "is this thing actually initialised?" to the top of your debugging list, before you go anywhere near the data.
## 2. State has to survive DOM it didn't create
The second thing you inherit is harder, and it's specific to server-rendered commerce.
In a React storefront the client owns the DOM. Cart state lives in a store, a mutation re-renders the subscribers, done. The framework's whole value proposition is that you describe state and never touch nodes.
On a server-rendered storefront, large parts of the page arrive as HTML from the server, and some of them arrive *again* after an interaction. Add to cart, and a section of markup is replaced wholesale by fresh HTML. Any JavaScript state attached to the old nodes goes with them.
So you need a rule about where state lives, and you need it before you write the second component, not after. Roughly:
- **State the server owns** (cart contents, customer group, prices) lives in a store the components read from, and gets refreshed from the server after a mutation.
- **State the component owns** (is this dropdown open, what's in this quantity input) lives on the component and is allowed to die with its markup.
Get that boundary wrong in the obvious direction and you get the classic bug: a mini-cart that shows the right total until you add a second item, then shows a stale one, because two components each kept their own copy and only one of them heard about the update.
React didn't solve this problem for you. It made it very hard to *express* the broken version, which is not the same thing but works out similarly in practice. Write the boundary down. A comment at the top of your store file naming what's server-owned is worth more than it looks.
## 3. Content Security Policy stops being someone else's config
This one only bites in a certain kind of project, but when it bites it invalidates a lot of code at once.
A build step gives you a CSP-friendly bundle almost by accident: your JavaScript ends up in files, so a strict `script-src` policy is satisfied without you thinking about it. Minimal setups tend to put behaviour in attributes, right in the markup, which is the whole ergonomic appeal: you can see what an element does by reading it.
Under a strict CSP that's a problem, because expressions evaluated at runtime look like `eval` to the browser. Alpine ships a CSP-compatible build precisely for this, and the tradeoff is that you can no longer write arbitrary expressions inline. Behaviour moves into registered component objects; the markup references methods and properties by name instead of evaluating logic.
It's a fine constraint. It's just one you want to know about on day one, because retrofitting it means rewriting every component you wrote in the ergonomic style. If your project is likely to need a strict policy (anything handling payment, anything where a security review is part of shipping), start in the CSP-compatible style even while nothing is enforcing it.
## When the trade is worth it
It's worth it more often than framework people admit and less often than the minimal-library posts imply.
The minimal approach wins when the server already owns most of the truth. A commerce storefront renders catalogue and cart data that lives in a database and is authoritative there. Shipping a client framework to re-derive state the server already computed is paying twice. That's why Hyvä works, and it's a structural reason, not a taste one.
It loses when the client is the source of truth: a configurator, a builder, a dashboard with heavy interdependent state, anything where the interesting state exists only in the browser and needs to stay coherent across many views. There, the framework's rendering model is the product, and hand-rolling it means writing a worse React with none of the documentation.
The useful question isn't "do I need React." It's: which of these three responsibilities am I ready to own? Initialisation timing, state across server-rendered DOM, and policy constraints on where code lives. If the answer is all three, drop the framework and enjoy the speed. If you haven't thought about them, you haven't removed complexity. You've moved it somewhere with no error messages.
---
_Source / further reading: https://pedroth.github.io/?p=post/NoNeedReact_
---
# The shipping rate your cart quotes is not the one you get billed
_Published 2026-08-06 · 6 min · Robin Dhiman_
_URL: https://devrob.in/blog/the-shipping-rate-your-cart-quotes-is-not-the-one-you-get-billed_
A store I worked on was quoting shipping at checkout from product weight alone. The numbers looked fine. Every order shipped. Nothing errored.
The margin on bulky items was quietly gone.
Couriers do not bill dead weight. They bill the **greater** of dead weight and volumetric weight, where volumetric weight is `L × B × H ÷ 5000` for most Indian carriers. A large, light parcel (a pillow, a lampshade, anything foam-packed) has a volumetric weight several times its actual weight. Rate on the scale reading alone and the store eats the difference on every one of those orders.
That part is not a secret. It is printed in the courier's own terms. The interesting part is why a competent team ships the wrong calculation anyway.
## The field that is marked optional
Open a courier's rate calculator and you will usually find a form roughly like this:
- Pickup pincode
- Delivery pincode
- Weight (kg)
- **Dimensions (Optional)**
Leave the dimensions blank and the calculator does not complain. It does not warn you. It returns a rate.
It also returns, in the breakdown, `Volumetric Weight: 0.00 KG` and an applicable weight equal to the dead weight you typed. The quote that comes back is the dead-weight quote: for a bulky parcel, roughly half of what the courier will actually invoice.
So the calculator is not lying. It answered the question you asked. You asked "what does a 2.86 kg parcel of unspecified shape cost," and the only honest answer to that is a dead-weight rate, because shape is the missing variable.
But nobody reads it that way. You read it as "what does my parcel cost," and the interface encouraged you to, by marking the input that changes the answer as optional.
## Why "optional" is the wrong word
There are two kinds of optional input, and interfaces routinely conflate them.
The first kind genuinely does not affect the result. A note on the order. A nickname on the address. Omit it and the number is identical.
The second kind affects the result enormously, but the system has a fallback so it does not have to stop. Dimensions are this kind. Omitting them does not remove volumetric weight from the pricing model. It substitutes zero and carries on. Zero is a valid number. It is arithmetically fine. It is also the single most optimistic value the field can take, so the resulting quote is not merely wrong, it is wrong in the direction that looks best.
The general shape:
> An input marked optional whose omission silently selects a default is not optional. It is a required input with a hidden, favourable answer pre-filled.
This is the same class of failure as a config flag that defaults to the permissive setting, or an ORM that silently coerces a bad string to `0`. No error, valid-looking output, wrong result. You only find out downstream, when reality disagrees with your number.
## What it costs
Run the arithmetic on a single parcel. A box 40 × 35 × 30 cm weighing 2.86 kg:
```
volumetric = (40 × 35 × 30) / 5000
= 42000 / 5000
= 8.4 kg
applicable = max(2.86, 8.4) = 8.4 kg
```
You quoted for 2.86 kg. You get invoiced for 8.4. On a courier slab priced per half-kilo, that is not a rounding error. It is roughly triple the weight you charged for.
Now notice what makes it hard to catch. The loss does not appear as a failed order or a support ticket. It appears as a courier invoice that is somewhat higher than expected, every month, spread across the subset of orders containing bulky items. There is no single event to investigate. It reads as "shipping is expensive," which is a sentence every merchant already believes.
## Fixing it in the catalog, not the checkout
The temptation is to patch the shipping calculation: clamp it, add a fudge factor, apply a percentage uplift to bulky categories. Don't. A fudge factor is a second wrong number chosen to cancel the first one, and it stops cancelling the moment the product mix changes.
The real fix is upstream and boring: **dimensions are catalog data, and they are mandatory.**
In Magento, `product.weight` exists out of the box and length, width and height do not. Whatever you do, the rating code needs all four. Something along these lines:
```php
public function applicableWeight(float $deadWeight, ?array $dims): float
{
if ($dims === null) {
throw new LocalizedException(
__('Cannot rate a shipment without dimensions.')
);
}
$volumetric = ($dims['l'] * $dims['b'] * $dims['h']) / self::DIVISOR;
return max($deadWeight, $volumetric);
}
```
The throw is the important line, and it is the one that gets argued about. A missing dimension is not a case to default through. It is a product that cannot be shipped correctly, and you would much rather learn that while adding the product than three weeks later on an invoice.
Two details worth pinning down before you write this:
**The divisor is per-carrier, and it belongs in config.** 5000 is common for Indian domestic courier services, but it is a carrier term, not a law of physics. Different carriers and different service classes use different divisors. Hardcode it and you have built the same silent-wrong-number bug one level up.
**Dimensions are the shipped box, not the product.** A folded garment ships flat, a rolled poster ships in a tube, and multiple items may consolidate into one carton. If your packing logic combines items, the volumetric calculation has to run against the resulting box, not against the sum of the products. Getting the divisor right and the box wrong leaves you exactly where you started.
## The check that generalises
The shipping bug is worth fixing. The habit behind it is worth more.
When a calculator, an API, or an admin form gives you a number you are going to make decisions with, ask one question before you trust it: **which inputs did I leave empty, and what did the system substitute?**
If the answer is "nothing, it ignores them," fine. If the answer is "zero," or "the default plan," or "the aggregate across all locations," you did not get an answer to your question. You got an answer to an easier one, and the difference between those two questions is where the money goes.
The rate calculator was never broken. It was doing arithmetic on the numbers it was given. The blank field was the bug.
---
_Source / further reading: https://github.com/mage-os/mageos-magento2/releases/tag/3.3.0_
---
# AI made writing code cheap. It did not make systems easier to reason about.
_Published 2026-07-25 · 7 min · Robin Dhiman_
_URL: https://devrob.in/blog/ai-made-writing-code-cheap-it-did-not-make-systems-easier-to-reason-about_
A question has been going around: if coding has been solved, why does software keep getting worse?
The usual answer is that AI writes sloppy code and we're all drowning in it. I don't think that's right. The generated code I review is mostly fine. It compiles, it has tests, it follows the conventions in the file it's sitting in. The problem is upstream of the code.
Writing code was never the expensive part of a mature e-commerce codebase. Reading one was.
## Two costs, and only one of them moved
Every change to a running system has two costs.
The **local cost** is producing the change: writing the class, the observer, the migration, the test. This is what code generation attacks, and it attacks it well. A task that used to take forty minutes of typing and doc-lookup now takes five.
The **global cost** is knowing whether the change is safe. What else fires when this event fires? Which of the eleven modules touching this area also modified this behaviour? Does the interceptor I'm adding run before or after the one the payment extension registered? Is there a cache layer that will serve the old value for the next six hours?
Code generation does almost nothing for the second cost. It can read files you point it at. It cannot tell you which files to point it at, because that knowledge isn't in any one file. It's distributed across a plugin registry, a set of XML declarations, a dependency-injection graph, and a database column somebody added in 2019.
When you cut one cost to near-zero and leave the other alone, the ratio between them changes. Changes get made faster than anyone can reason about them. That's the mechanism.
## Why extensibility is the thing that hurts
The platforms I work on daily are built for extensibility, and extensibility is precisely the property that makes global reasoning expensive.
Take a hook system, any hook system: WordPress filters, Magento plugins, Rails callbacks, Django signals, Laravel events. The design promise is the same: you can change behaviour without touching the original code. That promise is real, and it's the reason these ecosystems have tens of thousands of extensions.
The cost is that the call site no longer tells you what runs.
```php
$price = $this->priceCalculator->calculate($product);
```
What does that line do? You can't know from the line. In Magento 2 that method may be wrapped by any number of registered plugins across every installed module, each of which can rewrite the arguments, replace the return value, or skip the original entirely. The execution order is determined by a `sortOrder` attribute in XML files scattered across those modules. Reading `PriceCalculator::calculate()` tells you what the *original author* intended. It does not tell you what happens on this installation on Tuesday.
This is not a Magento complaint. It's the general shape. The abstraction that makes a platform extensible is the same abstraction that decouples the code you're reading from the code that runs.
## Where AI actually lands in that picture
So picture what an assistant does inside that architecture.
You ask for a change to how a price is calculated. The assistant reads the class, understands the class, and writes a clean, well-tested, conventional modification to the class. It is right about everything it can see.
It is not wrong. It is *locally* right in a system where local rightness was never the hard part. The eleventh plugin that quietly overrides the return value was never in the context window, because nothing in the file mentions it.
I've watched this play out on a store where a discount stopped applying. The change that broke it was correct code, correctly tested. It just ran at a point in the chain where a third-party module had already replaced the value it was reading. No test caught it, because every test mocked the collaborators, which is what unit tests do. The mock is a statement of what you *believe* the system does.
That's the loop that makes software worse: cheap local edits, unchanged global comprehension, and a test suite that validates your beliefs rather than the system.
## The move that has worked for me
The fix I've landed on is not "use AI less." It's to spend the time the assistant saved on the cost it didn't reduce.
Before accepting any change to shared behaviour, I make the global picture explicit: on paper, in the ticket, wherever. Concretely:
**Enumerate the interception points.** For the method being changed, list every plugin, observer, event listener, or preference registered against it on *this* installation. Not the ones you remember. The ones you can produce from the container. If you can't enumerate them, you don't know what your change does.
**Verify against the source of truth, not the docs.** I got burned badly enough by this to make it a rule: the installed vendor source is authoritative, and the documentation describes some other version. When a claim about framework behaviour matters, I read the vendor directory. Every time I've skipped that step to save ten minutes, it cost me an afternoon.
**Check the data layer separately.** Mocked tests never validate that a column exists. A query naming a field that lives on a different table passes every unit test in the suite and throws only in production. Read the schema.
**Write down the invariant.** Before hunting for problems, state what must stay true: "the sum of the line totals equals the order total," "this runs exactly once per order," "a released payment refuses if any refund is open." You can't find a violation of a rule you never named, and a change that preserves an unnamed invariant does so by luck.
None of that is new. What's new is that it used to be a smaller fraction of the work, because writing the code took long enough to force you to think about the system while you did it. That accidental thinking time is gone. It has to be replaced deliberately.
## The part I'm less sure about
I don't think this is permanent. An assistant that could walk a dependency-injection graph, resolve the plugin chain, and read the actual schema would attack the global cost directly, and the tooling is clearly heading that way.
But it's not a code-generation problem, and it won't be fixed by a better code generator. It's a system-comprehension problem. Until the tools model the system rather than the file, the split holds: generation is cheap, comprehension is not, and every hour you save on the first should be treated as an hour you now owe the second.
Software isn't getting worse because machines write bad code. It's getting worse because we removed the friction from the half of the job that was never the hard half, and mistook that for solving it.
---
_Source / further reading: https://ptrchm.com/posts/nothing-works-and-everyone-is-euphoric/_
---
# The Magento N+1 fix that hides your out-of-stock products
_Published 2026-07-23 · 5 min · Robin Dhiman_
_URL: https://devrob.in/blog/the-magento-n1-fix-that-hides-your-out-of-stock-products_
I had a category page doing something expensive. For every product in the grid it called `ProductRepositoryInterface::getById()` to read two custom attributes. That is the textbook N+1: on a category with 300 products, 300 separate product loads. The page felt every one of them.
The fix looks obvious. Stop loading products one at a time and pull them in a single collection query:
```php
$collection = $this->collectionFactory->create()
->addAttributeToSelect(['custom_a', 'custom_b'])
->addIdFilter($productIds);
```
One query instead of 300. The page got faster. And a few products quietly vanished from the result.
## getById() and a collection are not the same query
It is tempting to read the swap as "same rows, fewer queries." In the frontend area, that is not true. The two return different sets of rows.
Magento's `CatalogInventory` module attaches an in-stock filter to product collections in the frontend when the "Display Out of Stock Products" setting is off. Off is the default. So a plain product collection loaded on the storefront quietly excludes every out-of-stock product before your code ever sees it.
`ProductRepositoryInterface::getById()` does no such thing. Ask it for an out-of-stock product by id and you get the product. That asymmetry is the whole bug. The repository answers "does this product exist"; the frontend collection answers "is this product buyable right now," and nobody told you the question changed.
## Why it is silent
There is no exception. Nothing in the logs. The collection simply returns fewer rows than the ids you passed in.
If your code iterates the collection to build a map keyed by product id, the out-of-stock ids are not wrong values. They are missing keys. Any lookup that expects them falls through to its default branch. An empty label, a skipped badge, a price that never gets set, with no signal that anything went wrong.
That is what makes it dangerous. Every test written with in-stock fixtures passes. The failure only shows up on a real catalog, where some fraction of products is always out of stock, and it usually arrives weeks later as a vague "why is this product missing its custom label" ticket.
## The setting behind it
The switch lives at Stores > Configuration > Catalog > Inventory > Stock Options > Display Out of Stock Products. Under the hood it is `cataloginventory/options/show_out_of_stock`. Most stores leave it off, because most stores do not want to list things nobody can buy. That default is sensible for a category page and surprising inside your custom code.
The filter itself comes from `Magento\CatalogInventory\Helper\Stock::addIsInStockFilterToCollection()`, applied to storefront product collections. Knowing the method name is enough to grep for it and see exactly where the join gets added.
## Three ways out
**Need every product regardless of stock?** A frontend product collection is the wrong tool, or you opt out of the stock filter deliberately for that one collection. Do it explicitly and leave a comment, because the next person will assume the filter belongs there.
**Correctness matters more than the N+1?** Keep the repository. An N+1 across 300 products is a real cost, but returning the wrong data quickly is worse than returning the right data slowly. Measure before you assume the collection is the win.
**Want both?** Load the ids you actually need with a resource model or a raw select you control, instead of a catalog product collection that Magento has been quietly editing. You get the single-query speed without inheriting the storefront's stock semantics.
## The general lesson
The trap is not specific to inventory. Any time you replace a per-entity repository call with a collection to kill an N+1, you inherit whatever plugins, observers, and area-specific filters that collection carries. The speed-up is real. The "behaviour-preserving" assumption is the part to check.
A faster query that returns a different answer is not an optimisation. It is a bug with good latency.
---
# The Liquid you lint isn't the Liquid Shopify runs
_Published 2026-07-16 · 5 min · Robin Dhiman_
_URL: https://devrob.in/blog/the-liquid-you-lint-isnt-the-liquid-shopify-runs_
`shopify theme check` passed clean. The validator I run before every commit passed too. Then I opened the page on the dev store, and a size chart that builds its rows from a metafield rendered as one long, mangled line.
The Liquid was correct. The tool that checked it wasn't running the same Liquid that Shopify runs.
## Two engines, one language
Shopify's storefront renders Liquid with a Ruby engine, Shopify's own implementation, the one that has run the platform for years. Almost nothing you run locally uses it. `shopify theme check`, the Shopify MCP validator, and nearly every Node-based Liquid simulator run **LiquidJS**, a separate JavaScript reimplementation of the language.
So you have two implementations of one templating language. They agree on the overwhelming majority of what you write. They do not agree on all of it.
## Where they split
The gap I keep hitting is whitespace control. The trimming markers `{%-` and `-%}` strip surrounding whitespace, and the two engines don't always strip it identically. A few other rendering semantics differ too.
For what a linter is actually for, LiquidJS is faithful: syntax, undefined objects, unknown filters and tags, schema shape. A green run tells you the template parses and references things that exist. It does not promise byte-for-byte identical output.
## Why a few bytes of whitespace become a real bug
Most of the time you never notice, because HTML collapses runs of whitespace and the page looks fine either way. The exception is any code that treats rendered whitespace as data.
```liquid
{%- assign rows = product.metafields.custom.size_chart.value | split: row_delimiter -%}
{%- for row in rows -%}
| {{ row }} |
{%- endfor -%}
```
Split a rendered string on a delimiter and the exact whitespace decides where each field begins and ends. The same holds for a `` block, an inline SVG `path` you assemble in Liquid, or a JSON blob you build and hand to JavaScript. In all of those, an extra or missing newline isn't cosmetic. It changes the parse. That's how a table that's correct in my local preview shreds on the live storefront, or the reverse.
## Use the linter for what it catches
I still run theme check on every change, and you should. It catches the things it's built to catch: malformed syntax, undefined objects, unknown filters, schema errors. And, increasingly useful, it flags filters an AI assistant hallucinated into a template that don't exist. That's real value, and it's fast.
What it can't vouch for is whitespace-exact output. So the rule I follow is simple. Lint locally. When whitespace is load-bearing, render it on live Shopify, a dev store or a theme preview, before you trust it. Not the Node simulator. The engine that actually serves customers.
## The pattern underneath
This isn't really about Liquid. LiquidJS standing in for Ruby Liquid is one instance of a trap every engineer meets: the local stand-in that isn't the runtime. A mock that isn't the live API. SQLite in dev and Postgres in production. A cloud emulator on your laptop. Each one is close enough to be useful and different enough to lie to you at exactly the wrong moment.
The move isn't to distrust the tool. It's to know precisely which class of bug it can catch and which it can't, then send the rest to the real thing. For Liquid: lint in Node, render on Shopify.
---
# The docs were right — for a version I didn't have installed
_Published 2026-07-15 · 5 min · Robin Dhiman_
_URL: https://devrob.in/blog/the-docs-were-right-for-a-version-i-didnt-have-installed_
I was building a read-only admin grid over a custom entity. One row per record, two filters, no edit form. The kind of thing Magento's native UI components make you write 200 lines of XML for, so I reached for Loki AdminComponents (`loki/magento2-admin-components`), an Alpine.js-based grid framework that does the same job with a fraction of the markup.
The first filter I added threw on page load:
```
Field type "text" not found
```
I had copied that filter config straight from the module's documentation. The docs said `field_type="text"` was valid. The installed module disagreed.
## The docs and the code had drifted
Here is what actually happened. The documentation described a version of the module that was not the version sitting in my `vendor/` folder. Between the doc's examples and the release Composer had resolved for me (`0.6.2`), the accepted filter field types had changed. `text` was no longer one of them.
No amount of re-reading the docs would have surfaced that. They were internally consistent and completely wrong for my install.
The fix took two minutes once I stopped trusting the documentation and opened the source that was actually going to run:
```bash
grep -rn 'field_type' vendor/loki/magento2-admin-components/src
```
The installed code enumerates exactly which field types it accepts. I picked one that existed and the exception went away. Then I hit three more gotchas building that grid, and every one resolved the same way: not with a web search, but by reading the class in `vendor/` that Magento was about to instantiate.
## Why this keeps happening
Third-party Magento modules move faster than their READMEs. A constraint like `^0.6` pulls whatever minor the resolver picks, and the published docs usually track the main branch, not the tag you actually got. The gap between what the docs describe and what sits in your `vendor/` tree is where the afternoon goes.
AI in the loop makes this trap deeper, not shallower. A coding assistant that writes a filter config for you is drawing on whatever it absorbed about the module: the public docs at best, a stale blog post at worst. It will hand you `field_type="text"` with total confidence, because that used to be correct. It has no idea which minor version is pinned in your lockfile. Your `vendor/` folder is the only thing that does.
## The rule
For any third-party Magento module, the installed source in `vendor/` is the authoritative reference. The README is a hint. The docs site is a hint. The assistant is a hint. The class Magento is about to run is the fact.
Before I trust a config option from a module I don't control:
1. Open the class in `vendor/` that consumes the option.
2. Read what it actually accepts: the constant list, the switch, the constructor signature.
3. Match the config to that, not to the example I found online.
It feels slower. It is faster. Mocked tests won't cover for you here either: a unit test with a mocked dependency will happily accept a config the real class rejects at runtime, because the mock doesn't know the constant list moved. The ground truth is the installed code, not the thing standing in for it.
---
# You can't find a bug you never named
_Published 2026-07-14 · 6 min · Robin Dhiman_
_URL: https://devrob.in/blog/you-cant-find-a-bug-you-never-named_
There's a post going around arguing that every project should ship an `invariants.md`. I agree. What convinced me wasn't a blog post, though. It was a SELECT statement.
## The query that every test approved
In a review of a split-settlement module for a multi-vendor marketplace, a resource model built a query that read `base_shipping_refunded` off `sales_creditmemo`. That column isn't on the credit memo. It's on `sales_order`. The first real refund in production would have thrown.
The unit tests were green. All of them. The resource model was mocked, and a mock returns whatever you told it to return, including a value for a column that has never existed in any database anywhere.
Static analysis didn't care either. The column name is a string.
So the code cleared every gate we had, and the bug was still sitting in the diff, in plain sight, unremarked. Not because anyone was sloppy. Because nothing in the project stated the rule it broke.
## A finding is a violated rule
Here's the reframe that changed how I review code.
A bug isn't a smell or an ugliness. A bug is a specific statement about the system that is supposed to be true and isn't. "The settlement legs sum to what the customer paid." "The same webhook delivered twice moves money once." "Every column a query names exists on the table it names."
Which means: **you cannot find a violation of a rule you never wrote down.** A reviewer reading a diff cold is doing two jobs at once. Inferring what the system is supposed to guarantee, then checking whether this code breaks it. The first job is the hard one, and it gets redone, badly, by every person who opens the file.
Write the rules down once and reviewing collapses into a smaller task: take each statement, try to break it.
## What they actually look like
Not architecture. Not "the code should be clean." Falsifiable statements about state:
```markdown
# invariants.md (settlement)
CONSERVATION
- sum(settlement legs on an order) == the amount the customer actually paid.
- No path creates money. No path destroys it. A refund reduces legs; it never mints one.
IDEMPOTENCY
- Any gateway callback may be delivered twice. Processing it twice moves money once.
- Every write is keyed by the gateway's own reference, unique-constrained in the schema.
ORDERING
- A payout release refuses while any refund on that order is open.
- A leg never goes from settled back to pending.
ISOLATION
- One vendor's failed leg does not block another vendor's payout on the same order.
SCHEMA
- Every column a query names exists on the table it names. Verified against db_schema.xml,
not against a mock.
```
Each line is testable, arguable, and either true or false of a given code path. That last one exists purely because of the SELECT above. An invariants file is where you keep the scar tissue.
## Point the review at the list
The list earns its keep at review time, and it earns it twice over when the reviewer is a model.
"Look for bugs in this diff" produces plausible findings, and you spend the afternoon disproving them. "Prove none of these six statements can be broken by this diff, and give me the exact inputs that break the one that can" produces something you can act on. The rules give the review a shape, and they give you grounds to reject a finding that isn't anchored to one.
They also make disagreement useful. On that same review, two reviewers reached opposite conclusions about whether a credit memo could over-refund tax. Neither position was checkable against a vibe. Both were checkable against the invariant, and the invariant was checkable against the framework source. Reading the core class that registers a credit-memo item settled it in ten minutes: the refunded amount it tracks is tax-exclusive, so the over-refund was real.
A model's finding is a lead. The invariant tells you which lead is worth chasing. The source tells you whether it's true.
## Turn the ones you can into assertions
Some invariants become queries. Conservation is the obvious one:
```sql
SELECT o.entity_id,
o.base_grand_total,
SUM(l.base_amount) AS legs
FROM sales_order o
JOIN vendor_settlement_leg l ON l.order_id = o.entity_id
GROUP BY o.entity_id, o.base_grand_total
HAVING ABS(o.base_grand_total - SUM(l.base_amount)) > 0.01;
```
Zero rows means the money conserves. Run it nightly against production and a paragraph of intent has become an alarm.
Idempotency usually becomes a unique key rather than a test, which is stronger. If the gateway reference is unique in `db_schema.xml`, a redelivered webhook cannot insert a second leg no matter what the application layer does. Enforce it where it can't be forgotten.
Others stay prose. "One vendor's failure doesn't freeze another vendor's payout" was one we couldn't fully hold. The credit-memo freeze in that module is order-wide, so a dispute on one vendor's item does hold the rest. We shipped it anyway as a documented trade-off, and it got to be a decision instead of an argument only because it was written down as a named rule with a known blast radius.
## What this doesn't fix
An invariants file doesn't tell you the truth. It tells you what to check.
The schema rule is the clearest case. Writing "every column exists" changes nothing by itself. It becomes real when someone opens `db_schema.xml` and reads the table definition instead of trusting a green test. Mocked tests do not validate columns. They never have. That's the gate most reviews skip, and it costs about four minutes.
## The habit
Before the next module goes to review, write the file. Six to ten lines. What must always be true, stated specifically enough to be wrong.
Then review against it, and treat anything you find that isn't on the list as evidence the list is incomplete.
The bug I opened with was caught by reading a schema file, not by being clever. That's usually how it goes.
---
_Source / further reading: https://twitter.com/PiccoGabriele/status/2076876444760957440_
---
# The handshake tax: reuse your HTTP client in Magento integrations
_Published 2026-07-02 · 5 min · Robin Dhiman_
_URL: https://devrob.in/blog/the-handshake-tax-reuse-your-http-client-in-magento-integrations_
I had a product export that talked to a third-party pricing API. One product, fast. The full catalog was painfully slow. The database was barely doing anything, so I went looking, and the profiler pointed somewhere I didn't expect: the network, before a single request was even sent.
The code created a fresh HTTP client on every iteration of the loop.
## The handshake tax
Before you send one byte of an HTTPS request, the machine does a lot of quiet work.
A TCP handshake to open the socket. Then a TLS handshake on top: certificate exchange, key negotiation, several round trips across the wire. Only after all of that does your actual `GET` or `POST` go out.
Do it once and reuse the connection, you pay that tax once. Do it inside a loop over 40,000 products, you pay it 40,000 times. The request bodies are tiny. The setup is the whole bill.
## PHP tricks you into it
PHP is share-nothing. Every web request starts cold, so it feels natural to build a client, use it, and throw it away. For a single web request that hits one API once, that's fine. You were going to pay one handshake anyway.
The trap is the long-running process. A cron job, a `bin/magento` console command, a message-queue consumer syncing records to an ERP or a PIM. Those loop. And inside the loop, a lot of Magento integration code looks like this:
```php
foreach ($products as $product) {
$client = new \GuzzleHttp\Client(); // new connection every time
$client->post('https://api.example.com/sync', [
'json' => $this->toPayload($product),
]);
}
```
Every iteration opens a new connection, runs the full TCP + TLS dance, sends a few hundred bytes, and tears the connection down. The handshake runs N times for N products.
## Reuse one client
Guzzle keeps the underlying connection alive between requests made on the same client instance. So build it once, outside the loop:
```php
$client = new \GuzzleHttp\Client([
'base_uri' => 'https://api.example.com',
'headers' => ['Connection' => 'keep-alive'],
]);
foreach ($products as $product) {
$client->post('/sync', ['json' => $this->toPayload($product)]);
}
```
Same requests, same payloads. But now the socket and the TLS session are reused across the loop. You handshake once, then stream the rest over the open connection.
In a Magento module, go one step further and don't `new` the client at all. Inject a configured client, or a small wrapper service, through the constructor. The same instance gets shared, and the connection survives across the calls that matter.
## The louder version
In a long-lived runtime the same mistake gets worse. Create a client per call in a hot path and the cost compounds: on top of the repeated handshakes, you can run the machine out of outbound ports, because closed connections pile up in `TIME_WAIT` faster than the OS reclaims them. The service stops being able to open new sockets at all. Same root cause, much louder failure.
PHP's request model usually saves you from that specific cliff. It does not save you from the latency.
## How to find it
Grep your integration code for clients built inside loops, or hidden in a method that runs once per record:
```
grep -rn "new .*Client(" app/code | grep -i http
```
Look for any `new \GuzzleHttp\Client()` (or a raw `curl_init()`) sitting inside a `foreach`. That's the line paying the handshake tax on every pass.
Move the client up, out of the loop, and let the connection stay open. It's a one-line change. On a sync that touches thousands of records, it's the cheapest speedup you'll find all day.
---
# WooCommerce HPOS: when order sync floods Action Scheduler
_Published 2026-06-30 · 4 min · Robin Dhiman_
_URL: https://devrob.in/blog/woocommerce-hpos-when-order-sync-floods-action-scheduler_
A WooCommerce store starts misbehaving over a weekend. The database is swelling. The PHP error log is growing faster than the database. Background processing runs non-stop, and now you're seeing `Deadlock found` and `INSERT command denied` in the logs.
The usual suspects get blamed first. Redis. The page cache. That custom plugin you shipped on Friday. A recent server upgrade.
None of them are it.
## What's actually happening
If the store is on **HPOS** (High-Performance Order Storage, the order tables WooCommerce moved to a couple of years ago), there's a setting most people forget they enabled: compatibility mode.
HPOS keeps orders in their own tables (`wp_wc_orders`, `wp_wc_orders_meta`, and friends) instead of the old `wp_posts` / `wp_postmeta` layout. Compatibility mode keeps both stores in sync so legacy code that still reads `wp_postmeta` doesn't break. That sync runs through **Action Scheduler**, WooCommerce's background job queue.
Here's the trap. Every order change schedules a sync job. If anything is touching orders in a loop (an importer, a meta-rewriting cron, a plugin that re-saves every order on some hook), each touch enqueues another sync action. Failures get retried. The queue grows faster than the workers drain it, and Action Scheduler stores every one of those rows in your database.
That's your runaway table. That's your deadlock.
## Stop guessing. Query the queue.
You don't debug this by disabling plugins one at a time. The queue table tells you exactly what's being scheduled. Action Scheduler keeps its jobs in `wp_actionscheduler_actions`. Group them by hook:
```sql
SELECT hook, status, COUNT(*) AS n
FROM wp_actionscheduler_actions
GROUP BY hook, status
ORDER BY n DESC;
```
One hook will dwarf the rest. That hook name is your culprit — it tells you which subsystem is enqueuing work in a loop. You go from a vague 'something is wrong' to a named process scheduling hundreds of thousands of jobs, in one query.
This is the same move I make on Magento when `cron_schedule` or the message queue balloons: don't audit the whole stack, read the queue and `GROUP BY` what's piling up. The component generating the work always names itself.
## The fix
Two parts.
First, stop the bleeding. Once you've confirmed the store is fully on HPOS and nothing critical still reads the legacy tables, turn **off** compatibility mode under WooCommerce → Settings → Advanced → Features. You stop paying the sync tax on every order write. Don't flip this blind on a store full of legacy plugins. Verify they read HPOS first.
Second, clean up the backlog. Action Scheduler retains completed actions for 30 days by default, which is how a short burst leaves a long tail in your database. Lower the window with the `action_scheduler_retention_period` filter and let the cleanup task reclaim the space, or purge completed actions from Tools → Scheduled Actions.
## The lesson that travels
The platform-specific bit is narrow: HPOS compatibility mode is expensive under heavy order writes. Keep that one for WooCommerce.
The part that travels to every stack with a job queue: when background processing melts your database, the queue is the evidence, not the suspect list. Don't theorize about Redis. Count the rows by hook. Whatever is flooding you is already labelled.
---
# Enriching a large Magento catalog without melting the indexer
_Published 2026-06-26 · 6 min · Robin Dhiman_
_URL: https://devrob.in/blog/enriching-a-large-magento-catalog-without-melting-the-indexer_
Every few weeks the same question shows up in a Magento forum: thousands of SKUs, missing attributes, thin descriptions, no translations. How do I enrich all of it? The replies are always about sources. Icecat for attributes. An LLM for descriptions. A feed for the marketplace fields.
Sourcing the data has a thousand tutorials. Getting it into the catalog without taking the store down has almost none. That second part is the actual job.
## The mistake everyone makes first
You write the obvious loop. Load product, set value, save.
```php
foreach ($productIds as $id) {
$product = $this->productRepository->getById($id);
$product->setData('description', $descriptions[$id]);
$this->productRepository->save($product);
}
```
Every `save()` runs the full product lifecycle: validation, every save-after observer and plugin, and a reindex trigger. At 50,000 products you've fired that machinery 50,000 times. The script runs for hours, the indexer thrashes, and admin grinds while it does.
The product save path is built for a human editing one product in the admin. It is the wrong tool for touching the whole catalog.
## Set shared values in bulk
When you're writing the same value to many products (a marketplace flag, a country of manufacture, a default brand), Magento already ships the right tool:
```php
// Magento\Catalog\Model\Product\Action
$this->productAction->updateAttributes(
$batchOfIds, // 1-2k entity IDs per call
['country_of_manufacture' => 'IN'],
$storeId // 0 = default scope
);
```
`updateAttributes()` writes straight to the attribute's backend table for the whole batch and skips the full model save. One operation instead of N lifecycles. For genuinely distinct values per product, like unique descriptions, group your writes and keep them off the `productRepository->save()` path. The moment you're saving the full model in a loop, you've already lost.
## Put the indexer on schedule before you start
Switch your indexers to **Update by Schedule** before any bulk run.
On *Update on Save*, every write reindexes synchronously and your enrichment job fights the indexer for the whole run. On schedule, writes drop into the changelog and mview reindexes only the changed rows on cron. You enrich fast, then reindex the delta once.
```bash
bin/magento indexer:set-mode schedule
```
## Translations live at store-view scope
A translated description isn't a column on the product. It's an attribute value scoped to a store view. Write German to the German store view's id, not to the default scope. And don't clobber the default value with one language while you're at it.
That `$storeId` argument on `updateAttributes()` is the same lever: pass the store-view id to set the localized value, and leave the global value alone.
## The AI part, on a short leash
An LLM will draft decent product copy across thousands of SKUs in one pass. It will also state, with total confidence, that a cable is 2 metres, a shirt is 100% cotton, and a case fits a phone it has never heard of.
So treat generated copy as a draft, never as truth:
- Generate into a staging field or a disabled scope, not straight onto the live product page.
- Sample-review a real slice before you trust the batch.
- Keep anything load-bearing (dimensions, materials, compatibility, claims) sourced and verified, not generated.
A wrong spec on a product page is a returns problem, and on regulated goods it's a bigger one than that.
## An order of operations that survives 50k SKUs
1. Indexers to **scheduled**.
2. Enrich into staging: a holding field or a disabled scope nobody can see yet.
3. Bulk-apply in batches of 1-2k IDs, off the full save path.
4. Reindex the delta, then smoke-test a real sample of product pages.
5. Only then flip visibility.
The data sources are the easy 20%. The catalog is a live system with an indexer, a cache, and customers on it. Enrich it like one and 50,000 SKUs is a non-event. Loop over `save()` and you'll find out how long an afternoon can be.
---
# Three reasons a Tailwind v4 utility silently does nothing in Hyvä
_Published 2026-06-25 · 5 min · Robin Dhiman_
_URL: https://devrob.in/blog/three-reasons-a-tailwind-v4-utility-silently-does-nothing-in-hyva_
I was deep in a Hyvä v3 theme rebuild, running Tailwind v4. One bug kept coming back wearing a different mask each time. I'd write a utility class, reload, and nothing happened. The element ignored me. My first instinct was always the same: "something more specific is overriding it."
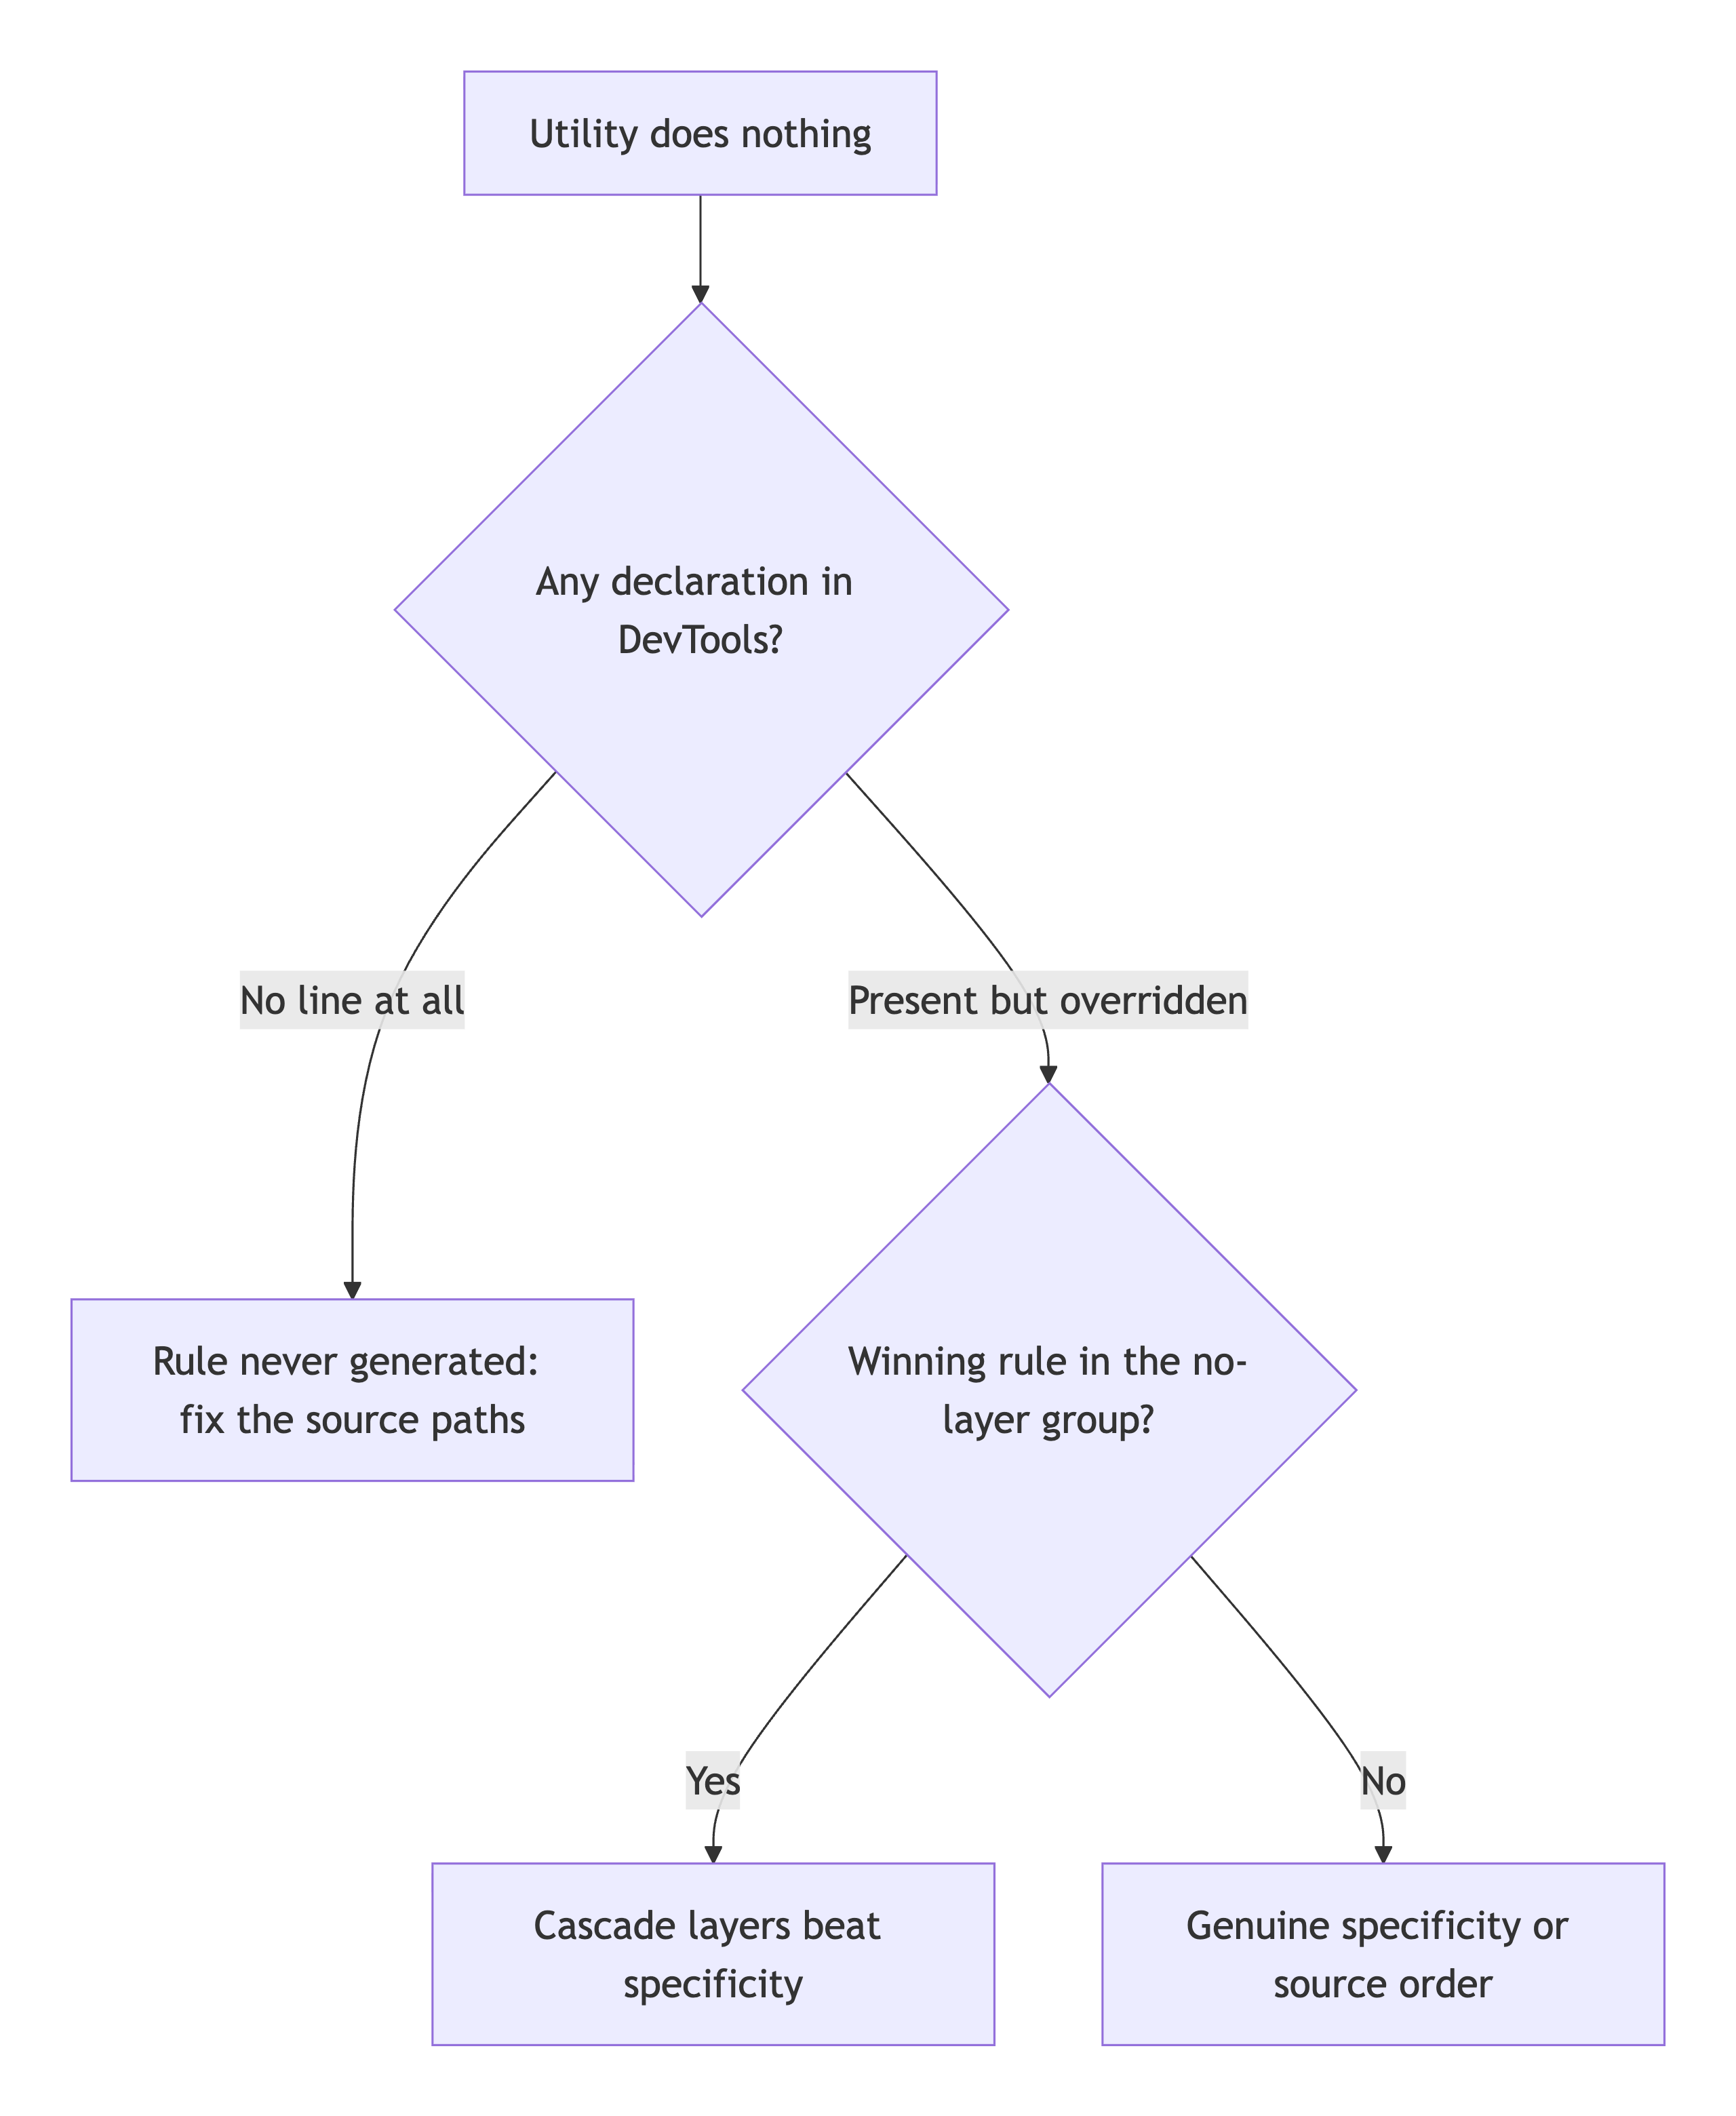
It almost never was.
Over the foundation work and then the homepage, I root-caused this "my class does nothing" symptom three separate times. Three different mechanisms. Two of them look exactly like a specificity fight but are not. Here's how to tell them apart in seconds instead of squinting at the cascade in DevTools for twenty minutes.
## 1. The rule was never generated
This is the Tailwind v4 trap that catches everyone coming from v3.
In v4 you can switch off automatic content detection with `source(none)`, then register what Tailwind should scan using `@source`. Hyvä leans on this so the compiled CSS stays lean.
The trap: use a utility in a template that no `@source` path covers, and Tailwind never sees the class. It never generates the rule. So `class="mt-8"` sits in your markup pointing at CSS that does not exist.
Open DevTools. The element has the class. There is no `margin-top` declaration anywhere, not struck through, just absent. That absence is the tell. A specificity loss shows a crossed-out declaration. A missing rule shows nothing at all.
Fix: add the directory to `@source` and recompile. Most of the time the path glob was simply too narrow.
```css
@import "tailwindcss" source(none);
@source "../../**/*.phtml";
@source "../../**/*.html";
```
## 2. Cascade layers beat specificity
This is the sneaky one.
Tailwind v4 emits its utilities inside native CSS cascade layers. Layers carry a rule most of us never had to learn before: any unlayered CSS beats any layered CSS, whatever the specificity.
So a stray rule with no layer (a third-party module's stylesheet, a hand-written block you forgot to wrap) will beat your Tailwind utility. Your selector can be more specific and still lose. That is what makes it read as a specificity bug. You inspect both rules, yours looks like it should win, and it doesn't.
The tell is in DevTools: the winning rule sits in the no-layer group, your utility sits under a named layer below it. Once you know to read the layer column, it is obvious. Until you do, it is maddening.
Fix: move the offending CSS into a layer, or stop loading unlayered third-party CSS after Tailwind.
## 3. It actually is specificity
Sometimes the boring answer is correct.
A base-theme selector genuinely is more specific than your single utility. Or, the v4 twist, two utilities of equal specificity resolve by their order in the compiled stylesheet, not the order you wrote them in `class=""`. Writing `class="p-2 p-4"` does not guarantee `p-4` wins. The winner depends on where those rules land in the generated CSS.
This is the only one of the three where the old model still holds: compare specificity, later source wins ties. Which is exactly why it pays to rule out the other two first.
## The triage
When a utility does nothing, before you touch specificity:
1. No declaration at all in DevTools? It is #1. The rule was not generated. Fix `@source`.
2. Declaration present but the winner sits in the no-layer group? It is #2. Cascade layers. Move the loser into a layer.
3. Declaration present, winner more specific or later in source? It is #3. Real specificity. Now you can fight it honestly.
Two of the three were never a specificity problem. Knowing that turns a twenty-minute DevTools dig into a ten-second glance at the right column.
---
# A PHP login form that won't get you owned
_Published 2026-06-24 · 6 min · Robin Dhiman_
_URL: https://devrob.in/blog/a-php-login-form-that-wont-get-you-owned_
A login form is the most-copied, least-reviewed piece of PHP on the internet. Someone needs auth, they paste a tutorial from 2014, it "works," and it ships. Then it leaks.
I've reviewed a lot of these. The same five mistakes show up every time. None of them are exotic. All of them are one function call away from being fixed.
## 1. Hashing passwords by hand
If your code contains `md5()`, `sha1()`, or a salt you generated yourself, stop. PHP has had a real password API since 5.5.
```php
// On signup
$hash = password_hash($password, PASSWORD_DEFAULT);
// On login
if (password_verify($password, $hash)) {
// authenticated
}
```
`password_hash()` picks a strong algorithm (bcrypt by default, Argon2id if you pass `PASSWORD_ARGON2ID`), generates the salt for you, and stores the cost inside the hash string. `password_verify()` does a constant-time comparison, so you don't leak timing. You never handle a salt again.
When you raise the cost later, `password_needs_rehash()` lets you re-hash transparently on the user's next login.
## 2. Building the query with string concatenation
```php
// Don't
$sql = "SELECT * FROM users WHERE email = '$email'";
```
That's SQL injection, on the front door of your app. Use a prepared statement and let the driver escape:
```php
$stmt = $pdo->prepare('SELECT id, password_hash FROM users WHERE email = ?');
$stmt->execute([$email]);
$user = $stmt->fetch();
```
Select only the columns you need. `SELECT *` on a user row pulls fields you'll expose by accident later.
## 3. Not regenerating the session ID
This one is invisible until someone exploits it. If you attach the logged-in state to the same session ID the visitor arrived with, you're open to session fixation: an attacker who can plant a victim's session ID before login inherits the authenticated session after.
One line, right after the password checks out:
```php
session_regenerate_id(true);
$_SESSION['user_id'] = $user['id'];
```
Regenerate on login, and again on logout and any privilege change.
## 4. Telling attackers which half they got right
```php
// Leaks which emails exist
if (!$user) {
echo 'No account with that email';
} elseif (!password_verify($password, $user['password_hash'])) {
echo 'Wrong password';
}
```
Two different messages turn your login form into a user-enumeration oracle. An attacker scripts it to learn which emails are registered, then focuses on those.
Return one message for both cases:
```php
if (!$user || !password_verify($password, $user['password_hash'])) {
$error = 'Invalid email or password';
}
```
To close the timing gap when the user doesn't exist, verify against a dummy hash so both paths do the same work.
## 5. Letting them guess forever
`password_hash()` is deliberately slow, which buys you a lot. It does not stop someone running a few hundred guesses at one account. That needs rate limiting.
The cheap version: count failed attempts per email and per IP in a fast store (Redis, or an indexed table), then refuse or delay past a threshold. Reset the counter on success.
You don't need a library to start. You need a counter and a ceiling.
## The shape of a correct login
Put together, the whole thing is short:
```php
$stmt = $pdo->prepare('SELECT id, password_hash FROM users WHERE email = ?');
$stmt->execute([$email]);
$user = $stmt->fetch();
if (!$user || !password_verify($password, $user['password_hash'])) {
// generic error, bump the rate-limit counter
return $this->fail('Invalid email or password');
}
session_regenerate_id(true);
$_SESSION['user_id'] = (int) $user['id'];
```
No custom crypto. No string-built SQL. One error message. A fresh session. A counter on top.
None of this is new. `password_hash()` landed in PHP 5.5, prepared statements are older still, and `session_regenerate_id()` has been there the whole time. The tools are old and boring. The mistakes survive because the tutorials never caught up.
If you maintain a PHP app with hand-rolled auth, read your login controller today. The fix is usually five small edits, not a rewrite.
---
# Why Magento cart price rules get slow at checkout (and how to find the culprit)
_Published 2026-06-23 · 6 min · Robin Dhiman_
_URL: https://devrob.in/blog/why-magento-cart-price-rules-get-slow-at-checkout-and-how-to-find-the-culprit_
I have watched a checkout get slower every time the marketing team shipped a new promotion. Not the product page. Not the cart. The totals step: the recalculation Magento runs after every add, remove, or quantity change. Each new cart price rule added a little more lag, and nobody connected the rules to the slowdown.
Here is what's actually going on under the hood.
## Cart price rules run in PHP, on every recalculation
A cart price rule is not a stored discount sitting in a column. It is a tree of conditions and a set of actions that Magento evaluates at runtime.
Every time the quote changes, Magento recollects totals. Discount collection is one stage of that pass, handled by `Magento\SalesRule\Model\Quote\Discount`. During it, Magento takes the rules that apply to the current cart and validates each rule's conditions against the quote items.
That validation is PHP. A loop over rules, and inside it, condition checks against items held in memory. There is no single clever query that returns "the right discount." It is procedural evaluation, and it reruns on every recalculation of the cart.
So the cost scales with two numbers: how many rules apply, and how expensive each rule is to check.
## The pre-filter is doing more than you think
Magento does not evaluate every row in `salesrule`. The rule collection is narrowed first by website, customer group, coupon, and the current date before any conditions are checked. A rule scoped to one website and one customer group gets dropped early for everyone else.
This is the cheapest performance win available, and most stores ignore it. Start by counting what is actually live:
```sql
SELECT rule_id, name, from_date, to_date, sort_order
FROM salesrule
WHERE is_active = 1
AND (to_date IS NULL OR to_date >= CURDATE())
ORDER BY sort_order;
```
If that returns 200 rows and your business runs maybe a dozen real promotions, you have 188 rules being filtered on every cart change for no reason. Expired campaigns that were never disabled. "Temporary" rules from two years ago. Each one is still work.
Disable what you don't use. Scope what you keep as tightly as the campaign allows.
## Conditions are where the time goes
Not all conditions cost the same.
A condition on subtotal or quantity is cheap. The values are already on the quote. A condition that asks "does the cart contain a product in category X" is not. Category membership has to be resolved per item.
Worse are conditions on product attributes. When a rule references a product attribute, Magento has to make that attribute available on the items during validation. It tracks which attributes rules care about in `salesrule_product_attribute`, then loads them so the conditions can run. Reference a heavy or rarely-loaded attribute in a rule condition and you have added an attribute load to a hot path.
The lesson: build conditions out of data the quote already has. Reach for category and attribute conditions only when a campaign genuinely needs them, and know you are paying for them on every recalculation.
## The table everyone forgets: salesrule_coupon
Auto-generated coupon batches live in `salesrule_coupon`. Generate a million codes for a campaign and the table holds a million rows. Lookups by code are indexed, so a single redemption stays fast, but the table itself grows without bound because expired campaigns rarely get cleaned up.
Check its size. If it is large and most of the codes belong to dead campaigns, archive them.
## Finding the actual culprit
Two ways, fastest first.
**Binary-search the rules.** Disable half the active rules, reproduce the cart flow, measure. Narrow until one rule stands out. Crude, but it works in minutes and needs no tooling.
**Profile it.** Point Blackfire or Xdebug's profiler at a cart update and look at the time spent under the discount totals collector and the sales rule validator. The expensive rule shows up as the condition path that dominates.
You are looking for one of two shapes: too many rules being validated, or one rule whose conditions are doing real work per item.
## What I would do, in order
1. Count active rules. Disable the dead ones. This alone often fixes it.
2. Tighten scope (website, customer group, dates) so the pre-filter throws rules out early.
3. Audit conditions. Replace category and attribute conditions with cheaper ones wherever the campaign allows.
4. Check `salesrule_coupon` size and archive spent batches.
5. Only then reach for the profiler, with a specific rule in your sights.
Promotions feel like a marketing concern until they show up in your checkout timings. They run on every cart change, in PHP, and they compound quietly. Treat the rule table like code: review it, delete what's dead, and keep the conditions cheap.
---
# The EAV tax: why Magento product loads are slow
_Published 2026-06-16 · 5 min · Robin Dhiman_
_URL: https://devrob.in/blog/the-eav-tax-why-magento-product-loads-are-slow_
Open a product in Magento 2 and ask your database what just happened. A single `addAttributeToSelect('*')` load does not fire one query. It fires one per attribute backend type, plus the static columns, plus stock and media. The same flexibility that lets you add a product attribute from the admin with no schema migration is what makes a full product load expensive.
That is the EAV tax. Most of the "Magento is slow" reports I get handed are paying it without knowing.
## What EAV actually stores
A product is not a row. It is a row in `catalog_product_entity` for the static columns, and then its attribute values are scattered across typed value tables: `catalog_product_entity_varchar`, `_int`, `_decimal`, `_text`, `_datetime`. Each value row is keyed by `entity_id`, `attribute_id`, and `store_id`.
To rebuild one product with all its attributes, Magento reads across every one of those tables and stitches the rows back into an object. Add a store view and the store-scoped values double the work.
```sql
SELECT e.entity_id, var.value AS name, dec.value AS price
FROM catalog_product_entity e
LEFT JOIN catalog_product_entity_varchar var
ON var.entity_id = e.entity_id AND var.attribute_id = 73
LEFT JOIN catalog_product_entity_decimal dec
ON dec.entity_id = e.entity_id AND dec.attribute_id = 77
WHERE e.entity_id = 42;
```
That is two attributes. Now picture `*`.
## Why `addAttributeToSelect('*')` is the trap
`*` means every attribute in the set. On a category grid showing 36 products, the card needs maybe six fields: name, price, thumbnail, url key, status, visibility. With `*` you loaded sixty. The other fifty-four were read, joined, hydrated, and thrown away before the page rendered.
Name the columns you actually use:
```php
$collection->addAttributeToSelect([
'name', 'price', 'small_image', 'url_key', 'status', 'visibility',
]);
```
This one change is the single biggest win I see on slow listing pages. It costs nothing and it ships in five minutes.
## Stop rendering listings off the product collection
The deeper fix is to not reassemble products from EAV on a listing at all. Category pages, layered navigation, and search should read from the index tables and OpenSearch, not loop a collection that re-hydrates every card from the value tables.
Magento already maintains flattened index tables for this: `catalog_category_product_index` for membership, the price index for prices, the fulltext index for search. A tuned category page leans on those and only touches EAV for the handful of attributes the card template prints. If your category controller is iterating a product collection with `*`, that is the thing to pull apart first.
## The flat catalog is not your escape hatch
Older Magento answered EAV cost with the flat catalog: denormalize every attribute into one wide `catalog_product_flat` table and read a single row. Adobe deprecated it, and for good reason. It falls over the moment you have thousands of attributes because MySQL caps columns per table, and it adds a heavy indexer you have to keep green. On a current build, do not turn it on.
## What I do instead
Select named attributes, never `*`, in any collection that renders to a user. Push listing and filtering to OpenSearch so the storefront reads an index instead of replaying joins. For bulk reads like exports and feeds, walk the catalog by `entity_id` with keyset pagination and select only the fields you need, because a full `*` load across a six-figure catalog will melt the box.
Then measure. Turn on the query log and count statements per request. When a single category page fires several hundred queries, EAV reassembly is almost always the reason, and now you know exactly which line put them there.
---
# Migrating a Magento 2 store from utf8 to utf8mb4 without losing data
_Published 2026-06-13 · 6 min · Robin Dhiman_
_URL: https://devrob.in/blog/migrating-a-magento-2-store-from-utf8-to-utf8mb4-without-losing-data_
A customer signed up with an emoji in their display name, and the row saved with everything after the emoji chopped off. No error in the log. The column was `utf8`, and in MySQL `utf8` has never been real UTF-8.
## `utf8` is a three-byte lie
MySQL's `utf8` is an alias for `utf8mb3`: at most three bytes per character. It covers the Basic Multilingual Plane and stops there. Emoji, many CJK extension characters, and a pile of modern symbols are four bytes, and they do not fit.
What happens when a four-byte character lands in a `utf8mb3` column depends on your SQL mode. In strict mode you get `Incorrect string value: '\xF0\x9F...'`. Without it, MySQL silently truncates the string at the offending byte and saves the rest. The second case is the dangerous one: no error, partial data, found weeks later in a support queue.
`utf8mb4` is the fix. It is actual UTF-8, up to four bytes per character. New Magento installs use it. Plenty of stores set up years ago are still on `utf8mb3` and inherit every one of these bugs.
## The migration looks like one line. It isn't.
The naive version:
```sql
ALTER TABLE customer_entity CONVERT TO CHARACTER SET utf8mb4 COLLATE utf8mb4_unicode_ci;
```
Run that across a real Magento schema and you hit this fast:
```
ERROR 1071 (42000): Specified key was too long; max key length is 767 bytes
```
An index on a `VARCHAR` column is sized in bytes, and MySQL budgets for the widest possible character. Under `utf8mb3`, `VARCHAR(255)` costs 255 x 3 = 765 bytes, just under the old 767-byte limit. Under `utf8mb4` the same column wants 255 x 4 = 1020 bytes, and the index is rejected.
Two ways out, and which one you need depends on your MySQL version:
- **MySQL 5.7 with `innodb_large_prefix` enabled, or MySQL 8.0** (where it is the default): the index limit is 3072 bytes on `DYNAMIC` or `COMPRESSED` row format. Most columns just work. This is where you want to be.
- **Older or misconfigured servers** still capped at 767 bytes: indexed string columns have to drop to 191 characters (191 x 4 = 764 bytes) or index a prefix. 191 isn't magic, it is just the largest count that still fits.
Check the row format before you start:
```sql
SHOW TABLE STATUS WHERE Name = 'customer_entity';
```
## The column is only half of it
Converting the column does nothing if the application still talks to the database as `utf8mb3`. Character set is negotiated on the connection. If the client opens with `SET NAMES utf8`, a four-byte character is mangled in transit before it ever reaches your new `utf8mb4` column.
So the migration is three coordinated changes, not one:
1. Database and tables: `ALTER ... CONVERT TO CHARACTER SET utf8mb4`. `CONVERT TO` rewrites the table and converts existing data, not just the default for new rows.
2. Server defaults in `my.cnf` (`character-set-server`, `collation-server`), so new tables are born correct.
3. The application connection charset, so reads and writes negotiate `utf8mb4` end to end.
Miss the third and you will swear the migration worked from the `mysql` CLI while the storefront keeps corrupting data.
## Two things that bite mid-migration
**`CONVERT TO` is a full table rewrite.** On a large `sales_order` or `catalog_product_entity_varchar` table that means a long lock. Do it in a maintenance window, or run it through `pt-online-schema-change` or `gh-ost` so the table stays writable.
**Collations have to match across joins.** Convert some tables and not others and the next query that joins them throws `Illegal mix of collations`. Pick one collation, apply it everywhere, and don't leave half the schema on the server default. `utf8mb4_unicode_ci` is a safe, widely compatible choice.
## The lesson isn't really about Magento
This is a MySQL story, not a Magento one. Any application sitting on `utf8mb3` carries the same latent bug and the same three-part fix. Magento just surfaces it early, because catalogs and customer data are full of exactly the international text and emoji that four bytes were invented for.
If you are still on `utf8`, you don't have a Unicode-safe store. You have one that hasn't met the wrong character yet.
---
# Which Magento extension is slowing you down? Stop guessing.
_Published 2026-06-12 · 7 min · Robin Dhiman_
_URL: https://devrob.in/blog/which-magento-extension-is-slowing-you-down-stop-guessing_
A store feels slow. Someone has installed forty extensions over three years. The usual advice is "disable them one at a time and see what helps." That is not debugging. That is guessing with extra steps, on production, with a fingers-crossed deploy at the end.
You can do better. Magento 2 makes the cost of an extension measurable if you know where it spends your time. Here is how I find the culprit instead of guessing.
## Where an extension actually costs you
A third-party module doesn't just "add features." On every request it can add work in four places:
- **Plugins (interceptors).** Every `` in a module's `di.xml` wraps a method. Magento compiles these into interceptor classes, and at runtime each one is a layer the call passes through: before, around, after. A module with twenty plugins on hot paths is twenty extra layers on requests that fire constantly.
- **Observers.** Each `` in `events.xml` runs when its event dispatches. Subscribe to something like `controller_action_predispatch` and your code runs on every single page.
- **Layout.** Layout XML is merged on page render. Blocks that a module injects into shared containers run their templates whether or not anyone looks at them.
- **Queries.** The quiet one. A block or observer that does "just one more lookup" per item turns into N more queries on a category page.
None of these are evil. They are how Magento is meant to be extended. The problem is volume and placement. Twenty cheap things on a page that renders a million times a day is not cheap.
## Step 1: turn on the profiler
Magento ships with a built-in profiler. Enable it:
```
bin/magento dev:profiler:enable
```
Set the output you want (the `html` profiler is the readable one) and load a slow page. You get a timing tree of the request: which methods ran, how long they took, how many times they were called. The "called N times" column is where extension problems hide. A method that runs once is fine; the same method at 1,400 calls is a loop someone didn't notice.
For anything serious, reach for a real profiler. Blackfire or Xdebug locally, New Relic or another APM in production. Blackfire in particular gives you a call graph where you can see time attributed to a vendor namespace at a glance. That namespace is your answer.
## Step 2: count what's actually attached
Before you profile, it helps to know what each module wires up. No tool needed. Just `grep` the vendor tree:
```
# plugins declared across all modules
grep -rl "getCookie('warmer_state');
$state = unserialize($payload); // attacker controls $payload
```
No exotic mistake. Just `unserialize()` pointed at something a visitor can set.
## The fix is boring, which is the point
**Don't serialize untrusted data with PHP's serializer at all.** Use JSON. It only carries data — arrays, strings, numbers — never objects, so there are no magic methods to trigger:
```php
$state = json_decode($payload, true);
```
In Magento 2 specifically, that's exactly what `Magento\Framework\Serialize\Serializer\Json` is for. Inject `SerializerInterface` and let it do the work — Magento deprecated raw `serialize()`/`unserialize()` in core for this reason years ago.
If you genuinely must unserialize PHP-native data, PHP 7+ lets you slam the door on objects:
```php
$state = unserialize($payload, ['allowed_classes' => false]);
```
That turns any embedded object into a `__PHP_Incomplete_Class` instead of instantiating it — no gadget chain, no `__destruct()` surprise. And if the payload crosses a trust boundary, sign it (HMAC) and verify before you even look at it.
## Auditing your own store
You can find most of this yourself in a minute:
```bash
grep -rn "unserialize(" vendor/ app/code/ \
| grep -v "allowed_classes"
```
Read every hit. For each one, ask the only question that matters: *can a user influence what reaches this call?* Start with extensions that touch caching, sessions, import/export, and anything that reads cookies — that's where the live ones hide.
## The wider point
None of this is really Magento's fault, and none of it is new. PHP object injection is a whole vulnerability class; Java has its own deserialization nightmare, Python has pickle, Ruby has its Marshal bugs. The lesson generalises cleanly: **deserialising attacker-controlled data into rich objects is remote code execution waiting for a gadget.** Treat any `unserialize()` (or `pickle.loads`, or `readObject`) on untrusted input as a live wire.
For Magento specifically, the uncomfortable part is that the dangerous code usually isn't yours. It rides in on an extension you installed to make the store *faster*. Your perfectly tuned cache layer is worth nothing if it hands an attacker a shell — so the next time you `composer require` a performance module, grep it before you trust it.
---
# Is your Magento store legible to AI assistants?
_Published 2026-06-12 · 7 min · Robin Dhiman_
_URL: https://devrob.in/blog/is-your-magento-store-legible-to-ai-assistants_
Ask ChatGPT or Claude for "a waterproof hiking watch with a barometer under 200" and you don't get ten blue links. You get a shortlist, with reasons. For a growing slice of shoppers, that shortlist *is* the storefront. They never reach a category page. Which raises an uncomfortable question for anyone running a catalog: when an assistant builds that list, is your store on it?
On Shopify, answering that is increasingly the platform's job. Shopify now ships an Agentic Storefronts page in the admin that feeds your catalog into AI channels like ChatGPT and Copilot, then reports which queries you surface for. You can argue about how well it works, but it's native: a toggle. On Magento there is no toggle. If you want a Magento store to be legible to an AI assistant, that's on you to build.
I spent the last few months building exactly that: a module that exposes a Magento catalog to AI crawlers and assistants. The work sorts cleanly into four layers. None of them are exotic. Most stores are missing all four.
## Layer 1: Let the crawlers in, deliberately
AI assistants are fed two ways: live retrieval at question time, and index crawls ahead of time. Both arrive as bots with their own user agents: GPTBot (OpenAI), ClaudeBot (Anthropic), Google-Extended, PerplexityBot, and a growing list.
Magento doesn't ship an opinion about any of them. Your `robots.txt` was written for Googlebot in a world that no longer exists. Step one is a decision, not code: which assistants are you willing to be read by, and have you actually said so? The mistake I see most is stores that block everything non-Google by reflex, then wonder why they're absent from AI answers.
## Layer 2: Give them machine-readable facts
A human reads "Was 180, now 140." A model inferring price, currency, and availability from rendered HTML gets it wrong often enough to drop you from a comparison.
This is where `schema.org` Product structured data earns its keep: JSON-LD with `price`, `priceCurrency`, `availability`, `gtin`, `brand`. Magento emits *some* structured data, but coverage is partial and theme-dependent. Hyvä, Luma, and every custom frontend handle it differently. The fix is unglamorous: audit what your product pages actually output as JSON-LD, and fill the gaps. Structured data was an SEO nicety for a decade. For machine readers it's the difference between a fact and a guess.
## Layer 3: Publish a map: llms.txt
[llms.txt](https://llmstxt.org/) is a proposed convention: a single Markdown file at your domain root that tells an assistant, in plain prose, what lives here and where the canonical version is. Think of it as a `robots.txt` written for comprehension instead of permission.
I'm deliberately measured about this one. Adoption is early, no assistant *guarantees* it reads your file, and anyone selling it as a ranking trick is overselling. But the cost is low and the logic is sound: when a model chooses what to retrieve, a clean Markdown summary of your catalog is far cheaper to parse than crawling a few thousand JavaScript-heavy product pages. You're doing the model's summarising for it, in your own words.
## Layer 4: Scale (and why Magento makes it hard)
Here it stops being a checklist and becomes engineering. A real catalog is 20k, 70k, 200k products. You can't dump all of it into one file, and you can't generate it by walking the catalog with naive `setCurPage()` pagination. That approach quietly falls off a performance cliff at depth. Generating an llms.txt or a machine feed for a large Magento store means keyset iteration, real curation (your best sellers and category structure, not every SKU), and incremental regeneration so you're not rebuilding everything on each cron tick.
That's the real reason this layer is missing from most stores: layers 1–3 are configuration, but layer 4 is a module someone has to write and keep correct as the catalog moves.
## The honest summary
This is early. The standards aren't settled, the assistants change behaviour monthly, and nobody can promise you a number. So don't treat AI discoverability as a growth hack; treat it as cheap table stakes you can get ahead of.
The platforms are already drawing the line. Shopify is making catalog-to-AI a built-in feature. Magento, true to form, hands you the primitives and a clean architecture and expects you to assemble the rest. That's annoying. It's also the opening. The Magento stores legible to assistants in 2026 won't be the ones that waited for a toggle. They'll be the ones whose team treated it as four small problems and shipped them.
---
# Paginating Magento catalogs without OFFSET
_Published 2026-04-19 · 6 min · Robin Dhiman_
_URL: https://devrob.in/blog/paginating-magento-catalogs-without-offset_
I was building a module that reads every product in a Magento catalog to generate an [llms.txt](https://llmstxt.org/) file. On a store with 70,000 products, the standard Magento collection was fast at page 1 and unusably slow around page 40. The code did not change — only the page number.
This is not specific to Magento. OFFSET pagination gets slower with page depth in every SQL database, and any ORM that exposes `LIMIT offset, n` inherits the same curve — Laravel, Django, Rails, Hibernate, all of them. `setPageSize()` and `setCurPage()` are the standard Magento 2 way to iterate a collection, so the pattern shows up a lot in Magento code. This post is about the fix.
## The standard way, and why it breaks
In Magento 2, if you want to read every product, you usually write something like this:
```php
$collection = $this->collectionFactory->create()
->addAttributeToSelect('*')
->setPageSize(1000)
->setCurPage($page);
```
Under the hood, `setPageSize` and `setCurPage` turn into SQL `LIMIT` and `OFFSET`:
```sql
SELECT * FROM catalog_product_entity
ORDER BY entity_id ASC
LIMIT 1000 OFFSET 999000;
```
MySQL reads this as: "start from row 1, skip 999,000 rows, then give me the next 1,000." The database has no shortcut. It walks the index from the start every single time.
That is the slowdown. At page 1, `OFFSET 0` is free. At page 1000, `OFFSET 999000` is 999,000 wasted row reads _per request_. The cost grows with the page number — and adds up if the same query runs many times.
## The fix, part one: keyset pagination
Instead of using OFFSET, use the index you already have — the primary key — as a cursor:
```sql
SELECT * FROM catalog_product_entity
WHERE entity_id > :lastId
ORDER BY entity_id ASC
LIMIT 1000;
```
This tells MySQL: "start from the row right after the last one I saw, and give me the next 1,000." It is an index range scan — the database jumps straight to the right spot through the B-tree. The cost is the same whether `:lastId` is 0, 10,000, or 1,000,000.
You pass the last `entity_id` you saw into the next query as `:lastId`. The cursor moves forward through the table without ever skipping rows.
Other teams have written about large speedups from this switch on production tables. The point is not the exact number — it is that the cost no longer grows with page depth.
Here is what it looks like in the module:
```php
private function buildProductSelect(int $storeId, int $lastId): Select
{
$select = $this->connection->select()
->from('catalog_product_entity')
->where('entity_id > ?', $lastId)
->order('entity_id ASC')
->limit(1000);
// ... EAV joins, status filter, visibility filter, etc.
return $select;
}
```
The `WHERE entity_id > :lastId` is the whole trick. Everything else is standard Magento code.
## The fix, part two: PHP generators
Keyset pagination solves the database side. But if you load 70,000 products into PHP arrays in one go, you have only moved the problem.
This is where `yield` helps. A PHP generator lets a function behave like an iterator — it hands back one batch at a time, pauses, and continues on the next call. Each batch can be freed from memory before the next one is fetched.
```php
private function getProductGenerator(int $storeId): Generator
{
$lastId = 0;
while (true) {
$rows = $this->connection->fetchAll(
$this->buildProductSelect($storeId, $lastId)
);
if (empty($rows)) {
break;
}
$lastId = (int) end($rows)['entity_id'];
yield $rows;
if (count($rows) < 1000) {
break;
}
}
}
```
The caller reads it like any other iterable:
```php
foreach ($this->getProductGenerator($storeId) as $batch) {
foreach ($batch as $row) {
// process one product
}
// $batch can be freed from memory here
// before the next batch is fetched
}
```
Memory per batch stays small — around 5–10 MB for 1,000 rows in my case. The database runs constant-cost range scans. The caller does not need to know how many products exist.
## One honest caveat
A generator keeps **per-batch** memory bounded. But if you collect results into a string or a big array across batches, **total** memory through the full loop still grows with catalog size — only the peak per fetch stays small.
So the full picture:
- **Database side:** truly constant cost per page, no matter the page depth
- **Per-batch PHP memory:** small and bounded
- **Total memory through the full loop:** still grows with catalog size, unless you also stream the output to disk
The first two are big wins on their own. Do not overstate the third.
## When to actually use this
Keyset pagination is the right default for any loop that:
- **Reads a large table from start to finish.** Catalog exports, data sync jobs, sitemap generation, search reindexing — anywhere the caller needs every row, not a slice.
- **Runs in a background job, cron, or CLI.** The sequential nature of cursor pagination is fine when nothing downstream needs to jump to an arbitrary page.
- **Uses a primary key that is a number and always goes up.** Magento's `entity_id` works this way — every new product gets a bigger ID than the last one, so `WHERE entity_id > :lastId` always moves forward without skipping or repeating rows.
It is _not_ the right tool when:
- **You need to jump to an arbitrary page.** Keyset pagination is sequential — to load page 50 you need the cursor value from page 49. There is no way to compute "the row just after position 49,000" without walking there first. Storefront product listings where a user clicks "page 27" directly still need OFFSET.
- **The sort column is not the primary key.** If users sort by price or name, duplicate values exist (two products at €9.99), so the cursor needs a deterministic tie-breaker. The `WHERE` clause becomes a pair: `WHERE (price, entity_id) > (:lastPrice, :lastId)`. It works and it is still fast, but the SQL is longer and the index needs to cover both columns in the right order.
- **The table is small.** Under a few thousand rows, OFFSET cost is lost in the noise. Stick with the default collection — extra complexity is not worth it.
## The one-line version
Use `WHERE pk > :lastId ORDER BY pk ASC LIMIT n` instead of `OFFSET`, and `yield` your batches from a generator function. Your catalog loops will stop slowing down as the catalog grows.
Source for the module that uses this technique: [github.com/iamrobindhiman/magento2-module-llms-txt](https://github.com/iamrobindhiman/magento2-module-llms-txt).
## Further reading
- [PHP: Generators overview](https://www.php.net/manual/en/language.generators.overview.php) — the official PHP docs on `yield` and generator functions
- [We need tool support for keyset pagination](https://use-the-index-luke.com/no-offset) by Markus Winand — the canonical argument against OFFSET, with SQL examples
- [MySQL: Optimizing LIMIT queries](https://dev.mysql.com/doc/refman/8.0/en/limit-optimization.html) — how MySQL handles LIMIT and OFFSET internally
---